Budget Pacing Strategies for Conversational AI Ad Campaigns
Conversational AI needs pacing models built on purchase intent, not time-of-day patterns.
Budget pacing in conversational AI advertising fails when it borrows assumptions built for a different kind of inventory entirely. That assumption holds reasonably well in channels where impression counts can be estimated ahead of time and spread across a day or week. It breaks down completely in a channel where the inventory itself is generated by the live content of a conversation, rather than by a fixed pool of queries or impressions waiting to be filled.
ChatGPT Ads budget guidance states the mismatch: inventory on conversational AI platforms is a function of conversation intent, not query volume. A media buyer accustomed to pulling historical search volume and backing into a daily budget has no equivalent data source to pull from here, because no keyword layer exists to measure in the first place. The targeting mechanism confirms why. Advertisers submit a natural-language description of the conversations where their ad belongs, and the platform matches that description against live conversation threads, prior chat history, and past ad interactions inside a relevance-weighted second-price auction. There is no pre-defined inventory pool sitting idle, waiting for a pacing curve to spread spend across it.
The practical consequence follows directly from that structural fact. A pacing model tuned to catch time-of-day peaks, or to spend in proportion to keyword auction volume, will burn through budget during conversation windows with little purchase intent and miss the windows where intent runs high, simply because neither signal the model reads has any relationship to when those high-intent conversations actually happen. Fixing that requires more than adjusting the dials on an existing pacing curve. It requires replacing the variable the pacing model tracks in the first place, and the sections that follow build toward exactly that replacement.
How conversational AI ad auctions work
Conversational AI ad inventory clusters unevenly across time, and it concentrates around the moments when conversations reach the comparison and decision stages of a purchase journey. Seeing why requires understanding what the auction actually rewards. The auction reads the advertiser's context hint alongside the ad's title, copy, and landing page, and relevance can outweigh a higher bid in determining placement. That single mechanical fact carries a large implication: inventory density depends on how closely live conversations match what an advertiser has described as their target context, not on how much that advertiser is willing to pay at a given hour.
OpenAI's own data, as reported in Pacvue's guide to ChatGPT Ads, shows that a meaningful share of ChatGPT conversations carry shopping intent, spanning categories including retail, home, beauty, travel, cooking, auto, electronics, and fitness. That share is not spread evenly across a user's day, and it is not spread evenly across conversation topics either. The same guide draws out the contrast with search in concrete terms: a typical Google search runs three to four words, while a ChatGPT prompt often runs a full paragraph, capable of surfacing a user's objective, their constraints, their context, and the tradeoffs they're weighing, all at once. The richer that prompt, the denser the intent signal buried inside it, and the more valuable the inventory window that prompt represents.
Three ad formats currently populate this auction environment, and their performance varies by where in the conversation they appear. Inline product cards tend to show up in comparison and decision-stage conversations, and they post the highest click-through rates of any current ChatGPT ad format. The format performing best sits exactly where the funnel-stage logic predicts it should, a point this piece returns to once the funnel allocation framework is laid out in full, since the pacing argument here isn't about optimizing creative for those formats.
One more mechanical fact belongs in this foundation. The auction ecosystem for conversational AI ads is still young, and competition for placements has not yet settled into stable, predictable pricing. Inventory availability can shift meaningfully from one day to the next as new advertisers enter the auction and the overlap between competing context hints changes. That instability gives time-based pacing logic one more way to misfire: even if a buyer somehow identified yesterday's high-intent windows, nothing guarantees today's auction looks the same.
Intent signals in conversational prompts and purchase stage
A multi-turn conversation reveals where a user sits in their purchase journey with a precision that keyword match and demographic targeting were never built to achieve. The variable worth tracking for pacing purposes is intent-signal density across the conversation funnel, not the hour on the clock.
Pacvue's guide places an old-style query next to its conversational equivalent, and the contrast is vivid. Where a search advertiser once worked from a bare phrase like "college dorm essentials," a ChatGPT conversation produces something closer to: "My son is starting college in the fall. He's living in a small dorm in the Northeast, and I want to make sure he has what he needs without overbuying." The second version hands a media buyer the user's objective, their constraints, their context, and the tradeoffs they're weighing, all in one statement, where the first version hands over almost nothing at all.
Whitebox's 2026 playbook describes the mechanism behind that richness directly: the system evaluates the full conversation thread, reading informational, comparative, and transactional intent layers together, which produces relevance signals substantially richer than anything a single search query can offer. Intent in this environment isn't a static label attached to a keyword. It builds turn by turn as the conversation unfolds.
That build produces three distinct intent tiers, and each one ties to a different stage of the funnel and a different auction dynamic. Exploration intent is at the upper funnel, where a user is gathering information without yet comparing specific options. Comparison intent sits in the middle, where a user is actively weighing alternatives against each other. Decision intent sits at the bottom, where a user is ready to act. Each tier carries a different expected return per dollar of ad spend, so that is the variable you should build a pacing strategy around.
Timing within the conversation itself affects when the highest-value pacing window occurs: available research shows users typically go about six prompts deep before they leave the conversation to convert on the open internet, though some categories, flights and electronics among them, see conversion happen faster. That pattern points to where the highest-value pacing window actually sits: the conversation arc from roughly the third prompt onward.
This has a direct consequence for how performance gets measured: if a channel shapes a decision that completes somewhere else entirely, last-click attribution models will understate conversational AI's actual contribution. Before launch, it makes sense to build a small set of proxy measures: branded search lift following exposure to the ads, assisted conversion rate inside a multi-touch attribution model, and lift in direct navigation traffic. None of these proxies closes the attribution loop completely, but together they give a team evidence that the intent signal is real and measurable, even when it doesn't convert on-platform.
Why funnel-stage budget allocation replaces time-based pacing
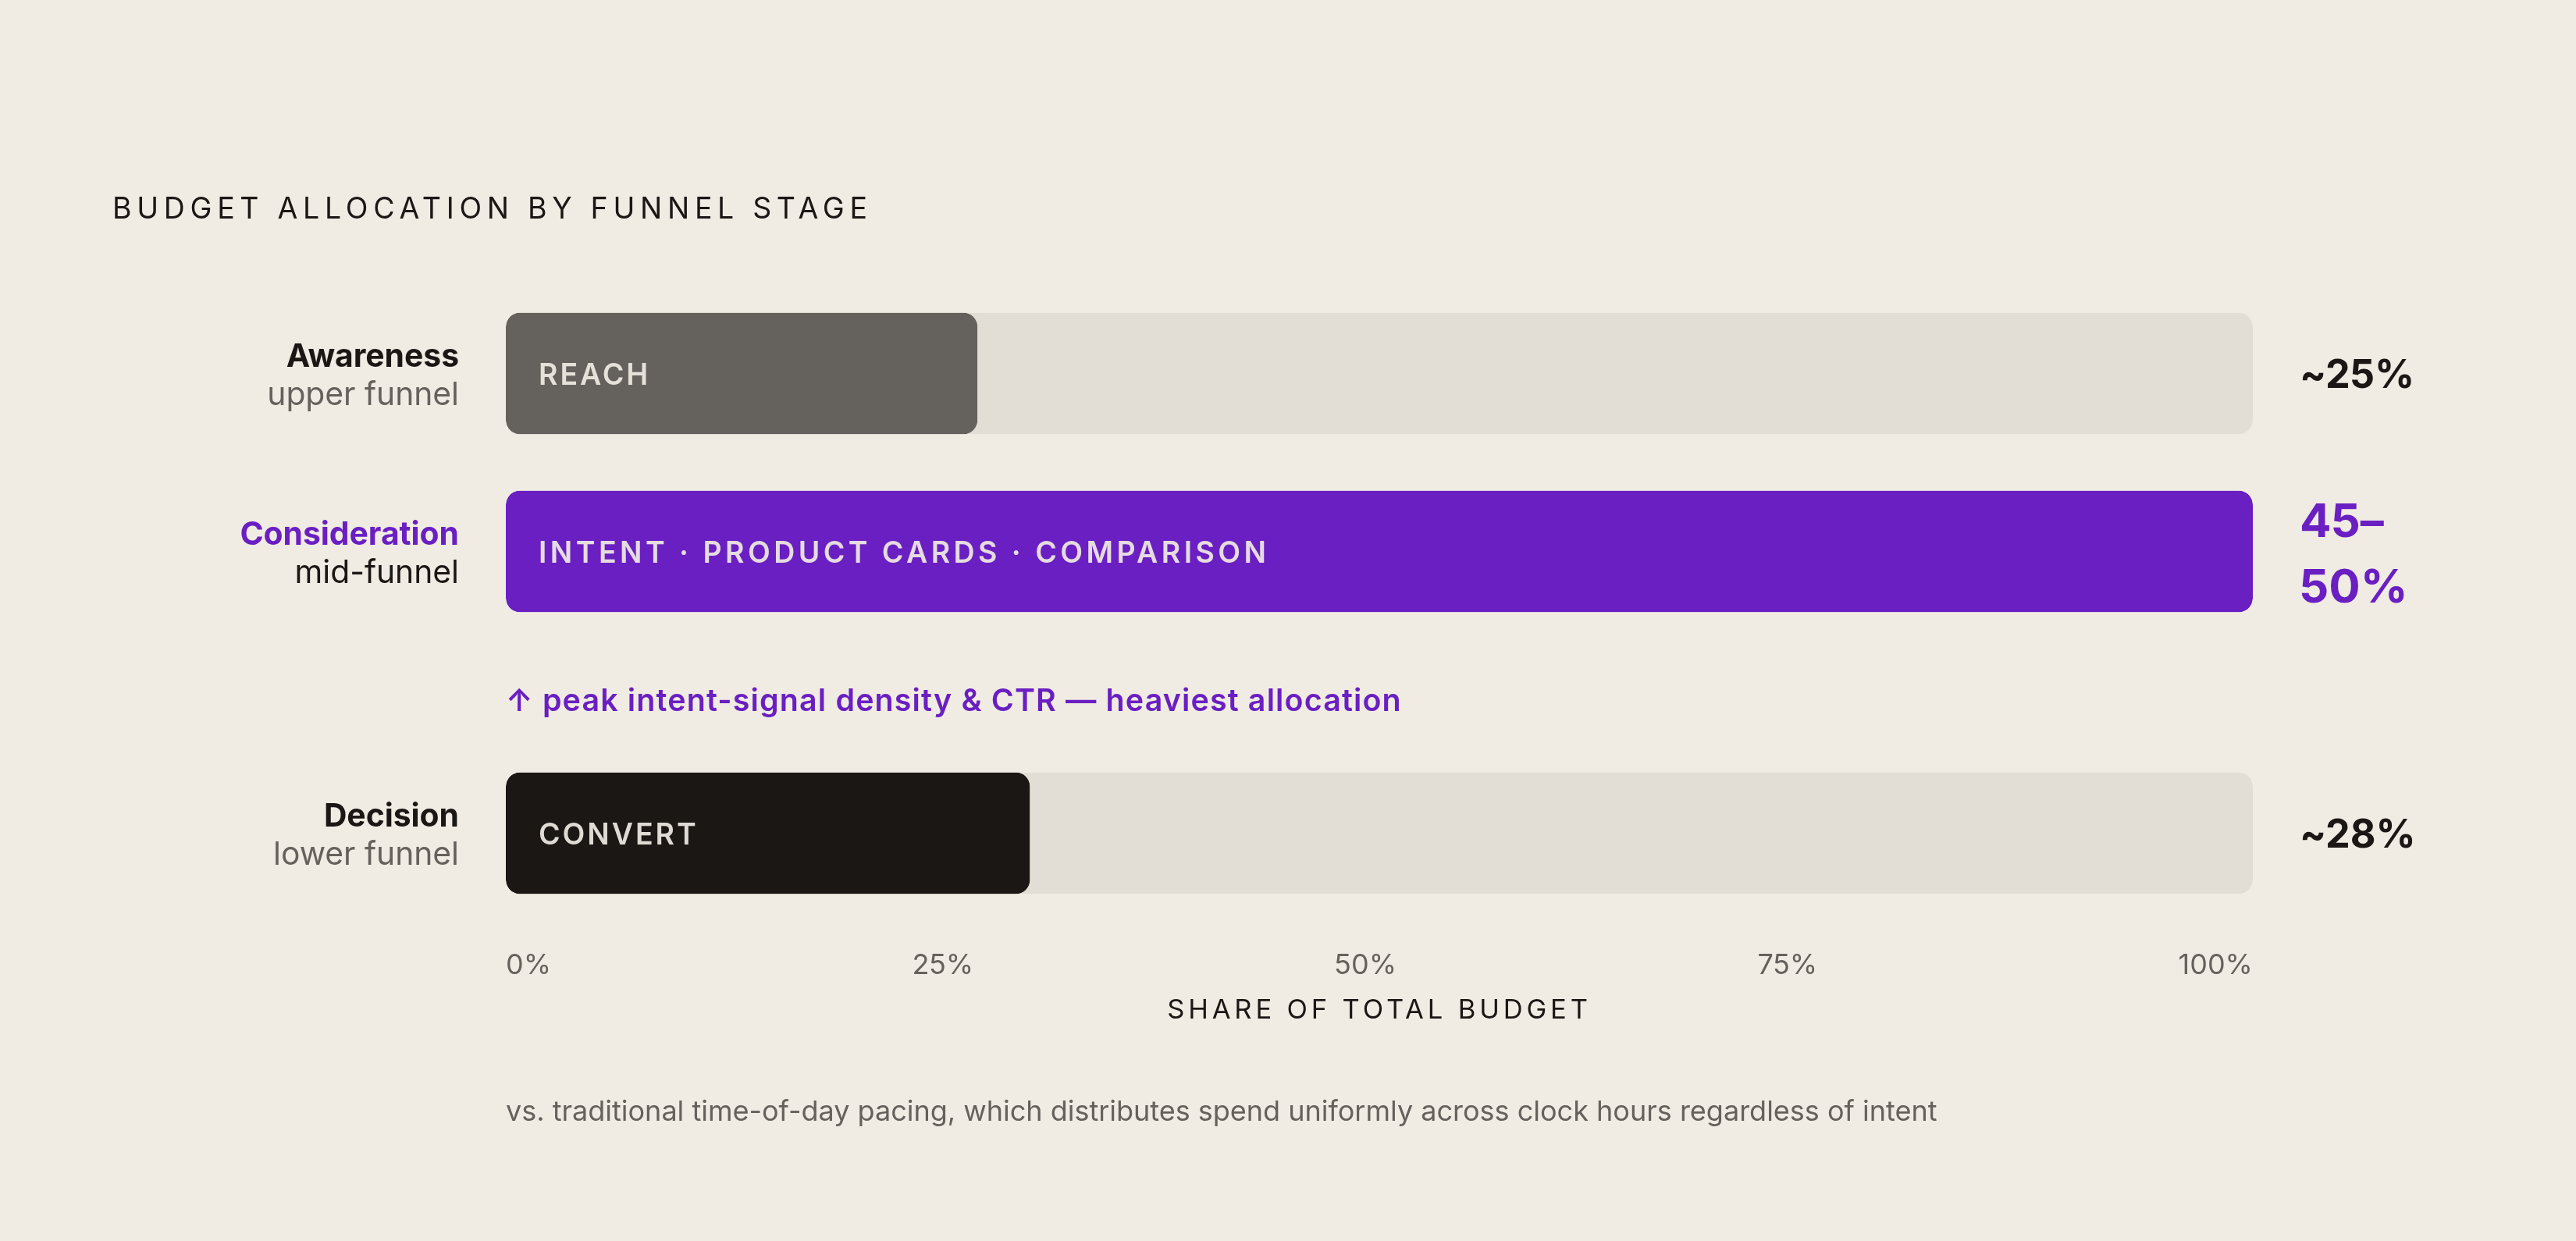
If intent-signal density clusters by funnel stage rather than by time of day, the pacing structure that follows logically is a budget envelope distributed across funnel stages, weighted toward whichever stage carries the densest purchase-intent signal, rather than a model that spreads spend evenly or front-loads it by the clock.
Practitioner consensus, drawn from current guidance rather than from any platform-endorsed setting, assigns the heaviest share of budget to consideration-phase conversations, the point where users are actively comparing options, requesting feature comparisons, and asking for direct recommendations. That share runs roughly 45 to 50% of total budget, with the awareness and decision phases splitting smaller shares on either side. These figures function as a starting point to test against actual performance data. The reasoning behind the weighting isn't arbitrary. Inline product cards, the format that tends to appear in comparison and decision-stage conversations, already post the highest click-through rates of any current ChatGPT ad format. Under-allocating budget to those conversation stages means under-allocating budget to the placements already proven to perform best.
Making that allocation work in practice requires the right structural container. A rigid daily cap applied at the campaign level recreates the exact problem this piece opened with: it forces spend against a clock instead of against intent. If you set a monthly budget envelope at the account level and allow flexible pacing across campaigns underneath it, the system can shift spend toward whichever funnel-stage campaign is seeing higher-intent inventory on a given day, with no artificial daily ceiling getting in the way.
A reasonable objection follows naturally from this structure. If high-intent conversations can't be predicted in advance, how can you be confident a monthly envelope gets spent efficiently rather than draining away during low-intent windows? The answer sits in the auction mechanics covered earlier: the relevance-weighted auction already filters for context match before a dollar gets spent. The job of the pacing structure is to make sure budget is sitting available when the auction finds high-intent inventory and matches it.
The learning-phase commitment that protects funnel-stage allocations from premature cuts
The matching algorithm behind this entire system is still learning how context hints map onto live conversations, so if you cut a campaign's budget during that learning phase, you destroy the very data the algorithm needs to make funnel-stage pacing work.
Current budget allocation guidance is specific about the timeline this requires: commit to the initial allocation for at least four to six weeks before making any significant cuts. If performance looks weak during that window, the fix is a creative or targeting adjustment, not a budget reduction, because any change that preserves spend keeps the learning process running. Cutting the budget instead simply starves the system of the volume it needs to learn.
Framing this correctly for stakeholders matters as much as following the timeline itself. The initial budget in this channel functions as a learning investment rather than a performance investment: an advertiser is buying data and early strategic positioning, not an immediate return on ad spend, and that framing needs to be set before launch or stakeholders will push for a shutdown the moment early numbers look thin.
Entry sizing varies by scale but follows a consistent logic. Practical entry sizing gives this context: one school of practice recommends starting at $50–$100 per day for at least seven days to establish baseline delivery data, while the enterprise view starts substantially higher, enough to baseline delivery, test context hints across each funnel stage, and let the system learn before scaling up. Current allocation guidance also frames this spend as an innovation budget: a defined share of total paid media spend set aside specifically for ChatGPT Ads exploration, with the exact percentage calibrated to how competitive the advertiser's category is and how much risk the organization is willing to carry.
The absence of historical benchmarks in this channel is a structural feature of where the channel sits right now, not a permanent condition, and that absence currently works in favor of advertisers willing to move early. Whoever establishes performance benchmarks first will effectively define the reference points everyone else measures against later, the same dynamic that rewarded advertisers who moved early into Google AdWords back in 2001. That asymmetry won't last. It exists because the auction is young, and it will close as more advertisers build their own benchmark data.
How demand-led pacing in adjacent channels validates intent-following logic
Google's move toward demand-led pacing in Search and Shopping offers evidence, from an adjacent channel, that pacing logic built around intent outperforms pacing logic built around uniform time-based delivery. Google announced the shift in May 2026, describing a system where its AI spends more on peak-demand days and less on slower ones automatically, capturing more of the available demand when it appears while staying within the monthly budget and daily spending limits an advertiser has set.
Josh Braverman, group product manager for Google Ads, described the underlying principle this way: "By pairing smarter bidding strategies with flexible budgets, you can capture high-value opportunities without the manual heavy lifting." The same logic applies directly to conversational AI advertising, with one difference in what counts as a high-value opportunity. In Google's system, high-value opportunities are defined by calendar-level demand spikes. In conversational AI, they're defined by which funnel stage a conversation has reached.
That difference points to a structural gap: Google's demand-led pacing tracks day-level demand signals that are legible from years of search volume history, data Google has accumulated at enormous scale. Conversational AI platforms have no equivalent historical query volume to draw on. That absence is why the intent-tier framework described earlier matters: it operationalizes demand-following at the level conversational AI actually exposes, the structure of the conversation itself.
The broader market signal supports the direction, even if the mechanism differs by channel. More than 30% of search ad spend now runs through AI-enabled campaign tools, a sign that advertisers across the industry are adjusting to conversational, context-rich queries generally. Both are abandoning time-uniform delivery in favor of pacing tied to where demand or intent actually concentrates.
Industry categories where funnel-stage pacing has the clearest immediate application
Categories built around complex, multi-step purchase decisions generate the richest comparison-intent conversations, so they stand out as the clearest first candidates for funnel-stage pacing, with the heaviest allocation and the highest stakes riding on the learning-phase commitment described earlier.
Travel, finance, health, and high-consideration e-commerce all share a category structure that produces this kind of conversation depth by default. A traveler asks ChatGPT to compare itineraries. Someone shopping for a major purchase asks for a feature-by-feature breakdown. Someone weighing a financial or health decision asks for a risk assessment before they commit to anything. Each of these interactions produces exactly the conversational depth that surfaces the highest-intent inventory described earlier in this piece, which makes the consideration-phase allocation the natural starting weight for advertisers in these verticals.
Whitebox's playbook offers a useful allocation principle across platforms more broadly: assign budget to whichever platform delivers the best cost-per-conversion for a given objective, using ChatGPT Ads to capture research-stage intent while relying on Google and Meta for retargeting and volume-driven goals. Applied to the funnel-stage framework, that principle implies the mid-funnel consideration allocation inside ChatGPT Ads should function as a discovery layer, surfacing a brand to a user who is actively comparing options, rather than a retargeting layer chasing a user who has already made up their mind.
Sportswear illustrates how this plays out in a category some advertisers might assume skews toward quick, low-consideration purchases. Research in this category shows a roughly even split between upper-funnel informational prompts and transactional prompts. The informational prompts carry buying signals that traditional search tools miss, because a user asking an open-ended question about running shoes is often further along in a purchase decision than the phrasing suggests. Upper-funnel spend in categories like this one carries more consideration-stage value than the "upper-funnel" label implies, which is a reason to test allocation weights against actual conversation data rather than assume the funnel-stage split from one category transfers cleanly to another.